What it protects
- The service itself, from more work than it can do.
- Other customers, from one customer's traffic.
- Costs, when each request costs money to serve.
- Login and sign-up forms, from guessing and abuse.
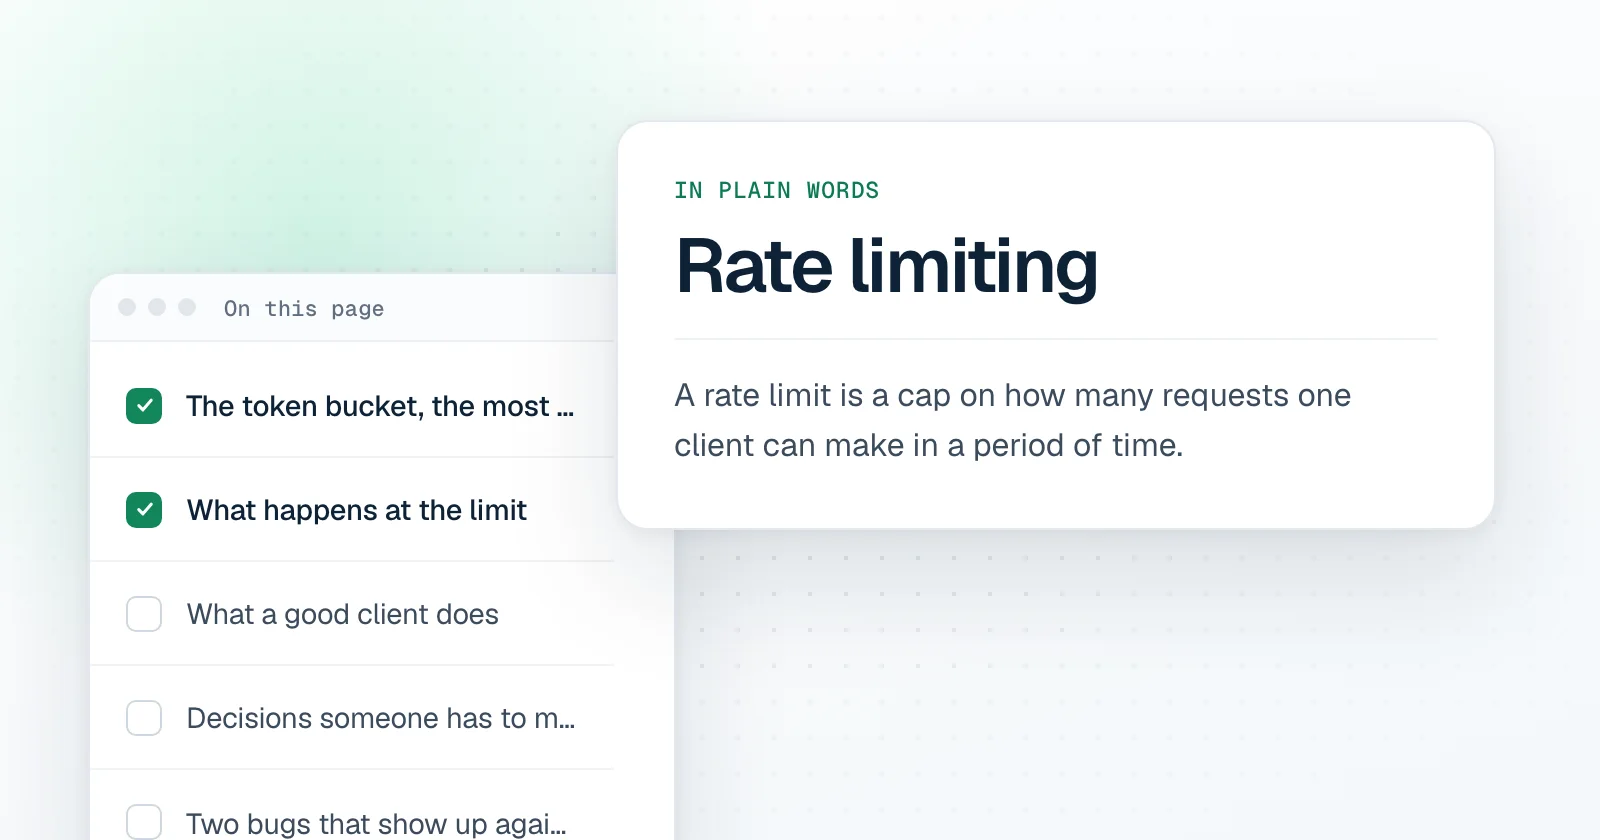
The token bucket, the most common design
Picture a bucket that holds up to ten tokens. Each request takes one token. Tokens are added back at a steady rate, say one per second, and the bucket never holds more than ten. A client that has been quiet can make ten requests at once. After that it is held to one per second.
- Capacity is the size of the burst you allow.
- Refill rate is the sustained speed you allow.
What happens at the limit
The service refuses the request, usually with the HTTP status 429, Too Many Requests, and often says how long to wait. Nothing is queued unless someone built that. The client has to come back.
What a good client does
- Reads the wait time the service gives, if there is one.
- Waits at least that long, with backoff if it happens again.
- Does not retry immediately. That is what got it limited.
Decisions someone has to make
- Per what? Per user, per API key, per IP address, per organization.
- Where is the count kept? In one server's memory it resets on restart and is not shared. In a shared store, every server sees the same count.
- Different limits for different actions? Reading is cheap. Sending email is not.
- What does the customer see? A clear message and a time to wait, or a mystery.
Two bugs that show up again and again
- Wrong units. Elapsed time in milliseconds multiplied by a rate per second refills the bucket a thousand times too fast.
- No cap. If refilling never stops at the capacity, a client that waits an hour gets an hour of tokens at once.
Both are in the code example in the debugging interview guide.
Questions you will hear in a meeting
- What is the limit today, and where is it set?
- Is it per user or per key?
- What do we return when someone hits it?
- Do our own background jobs count against it?